Most dependency scanners produce a number nobody can act on. Two thousand findings, sorted by severity, the overwhelming majority in code paths the application never executes. Teams triage for a week, then quietly stop looking — which is worse than not scanning, because now there is a false sense of coverage.
Status: product concept, in active development. This is something we are building, not something you can buy today. We publish our roadmap because the engineering thinking behind it is the useful part — and because we would rather show you the design than imply a finished product.
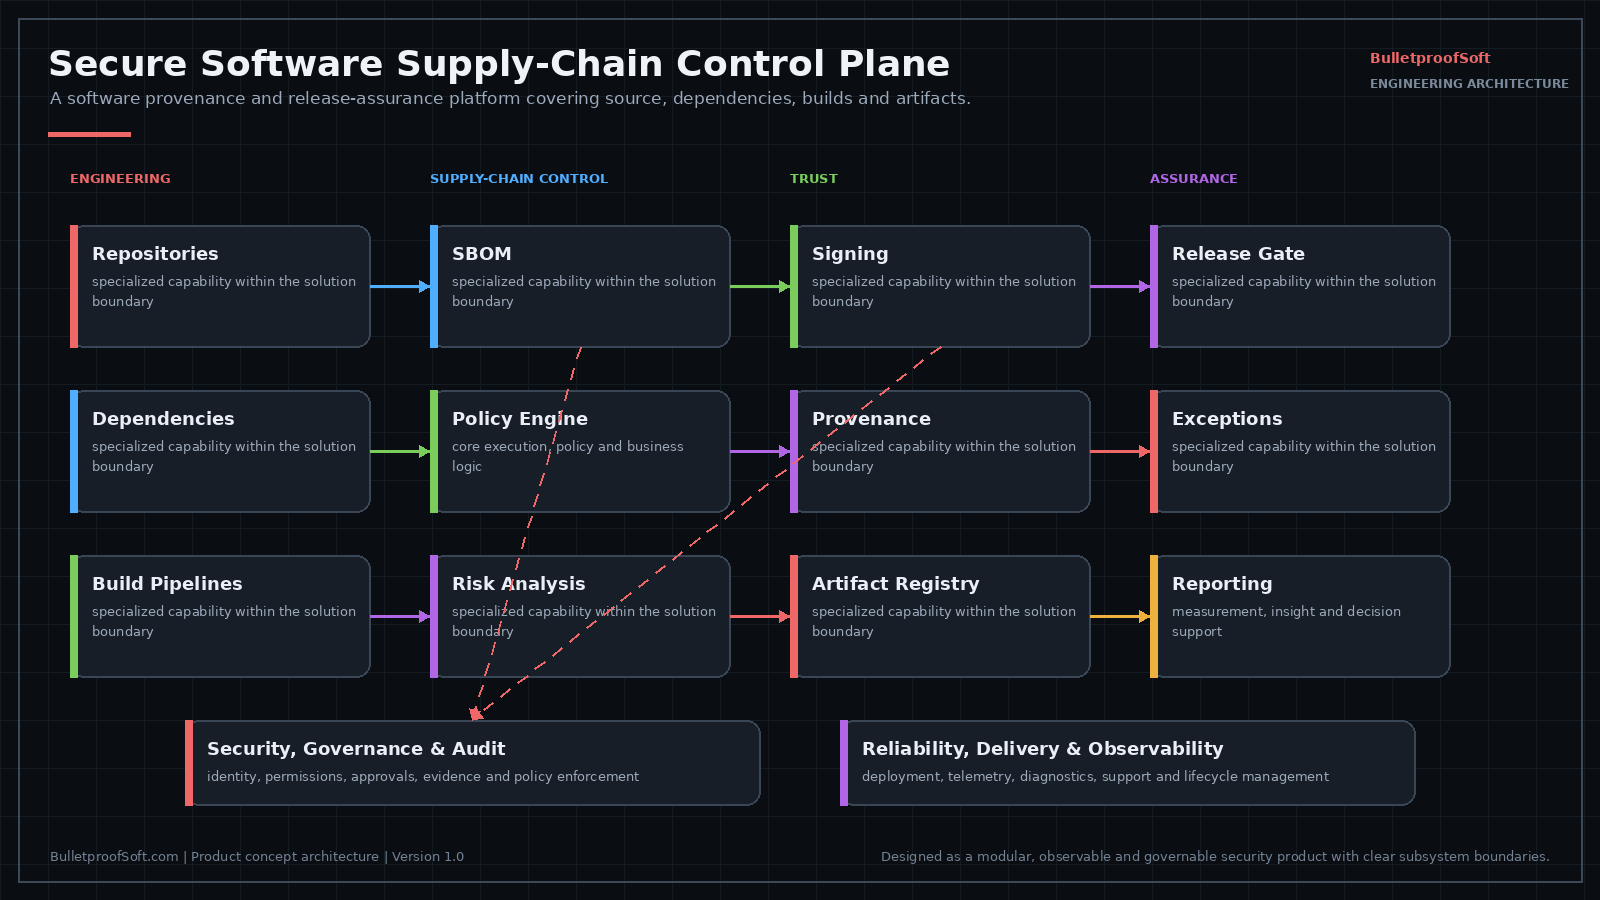
Designed Capabilities
- Repository and dependency inventory — know what is actually in the estate.
- SBOM generation and management — answer “are we affected?” in minutes, not days.
- Vulnerability and reachability analysis — is the vulnerable code path even called.
- License and policy checks — legal exposure caught before release, not during diligence.
- Secret and malicious-package detection — credentials and typosquats stopped at the gate.
- Signed build and provenance records — prove the artifact came from the reviewed source.
- Release approval workflows — the gate is policy, applied uniformly.
- Prioritized remediation and exception management — a short real list, with owned exceptions.
Reachability Is the Difference
Prioritising by exploitability and reachability rather than raw severity is what turns supply-chain security from noise into work that actually gets done. The underlying reasoning is covered in our article on securing the software supply chain.
Tell us if this matches a problem you have — early input shapes what we build first, and we will give you an honest view of where it stands.
Related services
- Security Compliance Readiness — Supply-chain evidence is increasingly an audit item: security compliance readiness.
Where This Sits Today
This control plane is a product concept in development. It is not something you can buy, license, or pilot from us today, no beta program is open, and no date is attached to one. The design is published so it can be argued with, and because a good deal of it describes work you could start this quarter with tools already in your estate.
What Does an SBOM Actually Answer?
It answers one question well: what is inside this artifact. When a widely used library turns out to be vulnerable, an accurate inventory tells you which builds contain it and which do not, and that is what makes the scramble tractable. It does not tell you whether you are exploitable, whether the component is reachable, or whether the artifact running in production is the one that was reviewed. A bill of materials is an input to a security control. It is not the control.
Where it comes from matters more than which format it uses. A bill of materials emitted by the build system reflects what shipped. One generated later by reading a manifest reflects what somebody intended to ship, which is a different claim and occasionally a much weaker one.
What Reachability Analysis Can and Cannot Settle
Prioritizing by whether vulnerable code can be called removes a great deal of noise, and what it settles is narrower than the marketing suggests. A call graph can show that no path in your code reaches the vulnerable function, which is a defensible reason to move an item down the queue. It cannot show that a path which does exist is ever executed, because there is no runtime context in a static view. Reflection, dynamic dispatch, plugin loading and configuration-driven paths all defeat it, and it sees little of a component reached only through a template or a deserialization format. The reasonable use is triage. An unreachable verdict is a scheduling decision, never a statement that the issue is harmless, and any tool presenting it as certainty is overselling the technique.
Signing Helps Only Where Something Verifies
Build provenance and artifact signing produce evidence: a record you can check afterwards and a third party can check independently. What they do not do on their own is prevent anything. Prevention starts when a deployment step refuses artifacts that are unsigned or unexpected, and enforcement is the part teams skip, because enforcement is where releases start failing at inconvenient moments. Key custody is the other half of the problem: signing keys living in the same CI environment an attacker would compromise do not prove much about the artifact. Pipeline identity is covered on our DevSecOps page, and the admission controls that turn a signature into a refusal are on our platform security page.
The Exception Register Is the Hard Part
Every program accumulates findings that will not be fixed soon, often for entirely legitimate reasons. What separates a working program from a dead one is whether each exception carries a named owner, a stated reason and an expiry date that forces it back into view. Without expiry, the exception list becomes the place findings go to be forgotten, and the report gradually stops meaning anything to anyone. Owners, reasons and dates are also the form this information has to be in before it can serve as evidence of risk acceptance, which is where this work meets security compliance readiness.
You May Not Need a Control Plane
A small estate with one build system and a handful of services can get most of the benefit from discipline: lockfiles committed and honored, a scheduled dependency update job whose test suite actually runs, secret scanning at commit time, and one person who reads the alerts. Tooling earns its place when the number of repositories makes that impossible to hold in one head, or when someone outside your organization starts asking you to prove any of it.
Frequently Asked Questions
What is the control plane, and what is it not?
It is designed to be the layer above the tools that already touch your code and artifacts: one inventory of repositories, dependencies, builds and released artifacts, and one place where policy is evaluated against that inventory. It is not a runtime security product. Nothing in the design observes production traffic or process behavior. It is also not a build system, an artifact registry or a package proxy, and it is not designed to replace the ones you run. And it cannot be bought, licensed, or deployed today.
What has to already exist on our side for this to work?
The design assumes four things on your side: source in a version control system with an API, a build system you can add a step to, somewhere to store artifacts that can hold a signature or attestation alongside the artifact, and a deployment step that can be made to refuse. The design also assumes an identity source behind approvals and ownership, because an exception owner has to resolve to a person who still works there, and a shared mailbox cannot be paged when a date passes.
How is rollout designed to proceed?
In an order where nothing can fail a release until you have decided it should. Inventory first, read only, since the first pass usually turns up repositories and build jobs nobody currently claims. Then policy in report-only mode, so you can see what a rule would have stopped across recent releases before it stops anything. Then SBOM generation moved into the build. Signing and admission checks come last. Each stage is designed to be reversible by turning enforcement off rather than by removing anything.
How is it designed to work with the scanners and CI we already run?
By attaching at four points rather than displacing anything: a step in the build, a read against the artifact store, a check at the deployment gate, and a write into whatever tracker your engineers already work from. Findings from scanners you already run are designed to be imported and merged with the control plane's own analysis into a single inventory, deduplicated by package and version rather than by finding identifier, because two tools rarely agree on identifiers and one component reached through two paths should not become two pieces of work.
What happens to our code, and what stays under our control?
Reachability analysis has to read code or compiled output, so that step is designed to run inside your build environment and emit the graph, rather than moving repositories anywhere. The control plane is designed to be deployable in infrastructure you control. It is designed to hold no signing keys itself: signing is designed to call out to a key custody system you own, so private key material never has to be present in the control plane's own environment. The exception register is your record, and it has to be exportable in full.
What do we have to decide?
The parts that are policy, not engineering. Which combinations of severity and reachability block a release and which only file an item. Which license classes are refused outright, which need review, and who does the reviewing. The maximum length of an exception and who is allowed to grant one. Whether artifacts built before rollout are grandfathered or blocked. And who owns a transitive dependency nobody chose. Defaults can be proposed for all of these, but they are starting positions to argue with, not settings to accept.
What can we start now with tools we already have?
Two pipeline steps do most of it, and neither needs a new product. First, have the build itself emit the bill of materials as a build output. Second, store it with the artifact rather than in a wiki page or a ticket. For container images, an SBOM or provenance document can be pushed to the same registry as a separate artifact that references the image by digest, using the OCI referrers API, so it is retrievable by anyone who can pull the image and does not drift when a tag moves. Pinning deployments to digests rather than tags costs nothing and removes a class of ambiguity.
What does the design have to get right to be worth running?
Traceability of its own answers. A verdict has to point back at the inputs that produced it: which artifact digest, which dependency graph, which vulnerability data as of when, and which version of the policy. Policy is therefore designed to be versioned, so a release approved two quarters ago can be re-evaluated against the rules in force at the time instead of today's. The same applies in the other direction: an inventory that quietly omits a package it could not parse is more dangerous than one that reports it as unknown, so unparsed inputs are designed to surface as gaps rather than as silence.