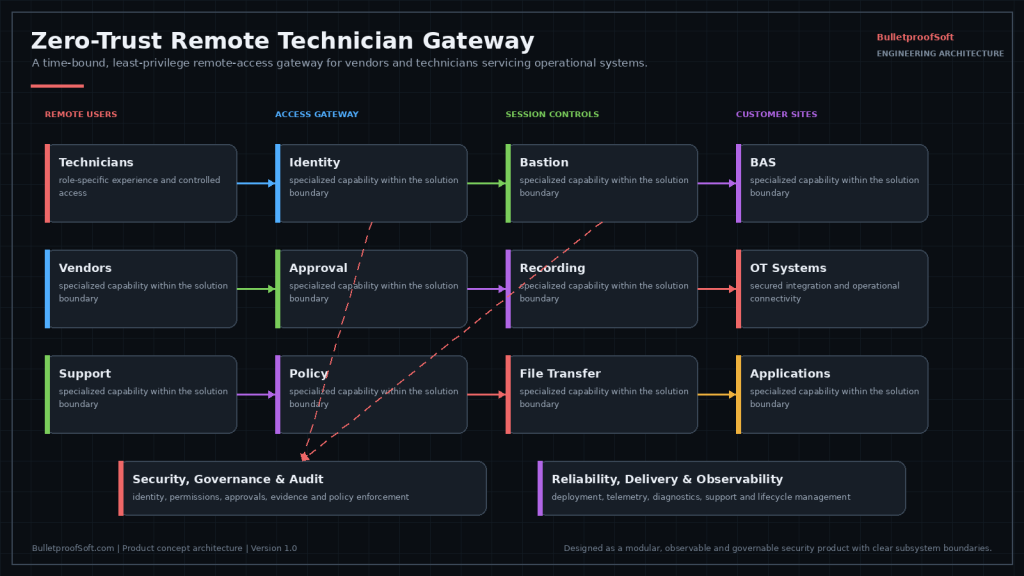
Remote access to building and industrial systems is usually solved with a shared VPN account, a jump box, and a great deal of trust. The vendor gets in, does the work, and the record of what happened is whatever they choose to tell you. When something breaks two days later, nobody can reconstruct who did what.
Status: product concept, in active development. This is something we are building, not something you can buy today. We publish our roadmap because the engineering thinking behind it is the useful part — and because we would rather show you the design than imply a finished product.
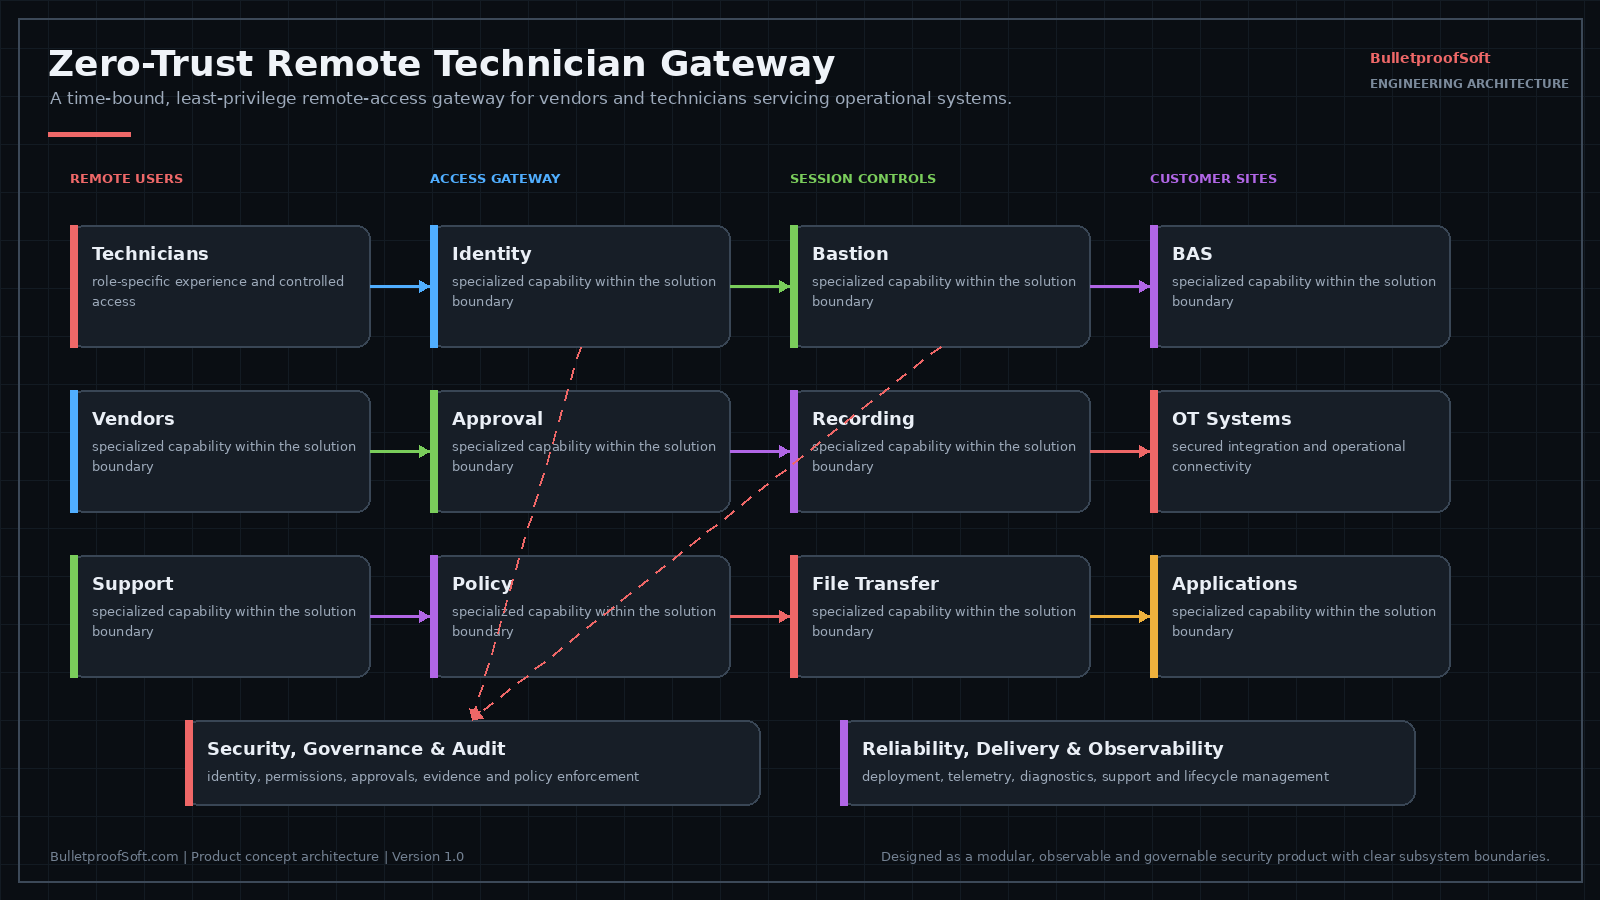
Designed Capabilities
- Identity and device verification — who, and from what machine.
- Ticket- and approval-linked access — access exists because a job authorised it.
- Site and application-level authorization — this site, this system, nothing else.
- Time-window and session policies — access expires on its own.
- Session recording and command logging — a reconstructable record of the work.
- Controlled file transfer — what came in and what left.
- Bastion and protocol proxying — no direct route to the control network.
- Customer asset and audit integration — access tied to the asset register.
Built for OT Realities
Operational networks cannot simply adopt corporate remote-access tooling — the systems are fragile, the vendors are numerous, and the access is occasional but highly privileged. Time-bound, ticket-linked, recorded access fits how this work genuinely happens, and complements the passive assessment side of our OT and network forensics practice.
Tell us if this matches a problem you have — early input shapes what we build first, and we will give you an honest view of where it stands.
Related services
- OT and ICS Security Assessment — Remote access is a finding in most control networks: OT and ICS security assessment.
This Is a Design, Not a Product Yet
This gateway is a concept we are building. It is not available to buy, license, or pilot today, no pilot program is open, and no release date is published. What follows is the reasoning behind the design, which is worth reading either way, because the same decisions apply to the remote access arrangements you have right now.
What Zero Trust Means for a Service Technician
Stripped of marketing, it means no standing access. A technician does not hold a credential that works on Tuesday because it worked last month. Access comes into existence because a work order exists, is scoped to the systems that work order names, carries an expiry, and leaves a record behind. Two properties do most of the work: access that ends without anyone remembering to remove it, and authorization bound to a specific site and system instead of a whole network segment. An account that outlives the reason it was created keeps working long after anyone has a reason to look at it, which is why expiry does more here than password policy does.
Session Recording Raises Questions to Settle Early
Recording a vendor’s work is defensible, but permission for it is not automatic. Notice obligations, consent, employee representation requirements in some jurisdictions, retention periods, who may review a recording, and what happens when one becomes evidence in a commercial dispute all need answers before the first session. Those answers belong to your counsel and your contracts team, and vendor agreements often predate the question entirely.
The design has to make those answers enforceable rather than aspirational, which is the part a product can fairly be judged on: a banner shown at session start, a retention period settable per site instead of rare full-stack Niagaraly, playback restricted to a named group with each view itself logged, and an export path for the one case where a recording is needed as evidence. A gateway that cannot express the policy your contracts team writes will have that policy broken within a month of go-live.
Break-Glass Is a Design Requirement
Any control placed between a technician and a plant becomes part of that plant’s availability story. If the gateway is unreachable at two in the morning during a heating failure, somebody will look for a way around it, and an undocumented workaround is worse than a documented one. Emergency paths deserve deliberate design: a separate credential route, heavily alerted, short-lived, and reviewed the next business day. What an outage actually costs varies enormously by facility and by the process being served, so the availability requirement is a conversation with operations before it is an engineering decision.
Why Operational Networks Make This Harder
Control systems are frequently old, rarely patched, and intolerant of scanning and agents. Vendors arrive with their own laptops and their own tooling. BACnet and Modbus were specified without authentication of their own; secure variants exist in BACnet/SC and in the Modbus/TCP security specification, but most equipment already installed does not speak them, so anything meaningful still has to happen at the access layer and the network boundary. Change windows are narrow, and a single integrator may hold access to many sites belonging to different owners. These are the conditions our OT and ICS security assessment work examines, and remote access is one of the first things that assessment looks at.
The Threshold Where This Starts to Matter
What changes the calculation is multiplicity: several vendors, several sites, any shared account, or an inability to say who connected last month and what they touched while they were in. Past that point the access list stops being something one person can hold in their head, and the review that was supposed to happen quarterly stops happening. Below it, what many sites already have is reasonable. One vendor, one site, individually named accounts with multifactor, an access list somebody actually reviews on a schedule, and logs that get read: a gateway would add process to that without taking much risk out of it.
Frequently Asked Questions
What is the gateway, and what is it not?
As designed, it is a brokered session path: a technician connects to the gateway instead of to your network, and the gateway opens a separate connection onward to one system. The useful part of the answer is the list of things it is not. It is not a VPN concentrator for your own staff. It is not remote monitoring or an RMM console, since it carries an interactive session and does not poll equipment or collect points. It is not an identity provider, it consumes one. It is not a scanner or an asset discovery tool, and it produces no inventory of its own. And it does not translate between protocols: no BACnet-to-Modbus conversion, no fieldbus bridging, because what it proxies is the session a technician opens, not the traffic a controller exchanges with its field devices.
What has to already exist on our side before any of this could work?
The prerequisites are yours, not the product's. An identity provider that speaks SAML or OIDC, with multifactor enrolled for the vendor's technicians as individuals rather than for a vendor login. A work order or ticket system with an API that can be queried for a ticket's state and the assets it names, because ticket-linked access is only as good as the field that says which system the job is about. An asset register whose site and system names are stable, since authorization scope is expressed in those names and an asset called three different things in three systems cannot be scoped. A network position where the gateway can reach engineering workstations and device interfaces while technicians can reach only the gateway, which usually means firewall changes rather than just a new host. And storage you control for recordings and command logs, with a syslog or SIEM destination for the audit events. The gateway is designed to consume all five. It is not designed to supply any of them.
How is a rollout designed to proceed, in order?
Inventory first: who has remote access to what today, including accounts created by an integrator that has since changed hands. Then connect the identity provider and enroll technicians as individuals. Then load site and system scope, so that a work order can name something the gateway recognizes. Then connect the ticket system in a report-only mode, where sessions are allowed and the ticket link is recorded but not enforced, which is where you learn how work orders are actually written as opposed to how the process document says they are written. Then enforce, on a narrow scope, with the old path still live. Then remove the old shared credential, which is the step that actually removes the risk and the one most likely to be postponed indefinitely. None of this can be run today; the order is the design, not a schedule.
Does anything get installed on the control systems themselves?
No, and that constraint shapes the rest of the design. The onward connection is designed to use the access method the target already exposes: RDP or VNC to an engineering workstation, SSH to a host, HTTPS to a device web interface. Nothing new runs on the controller. The consequence worth understanding is that the gateway then inherits the target's own authentication, which on a control network is frequently a shared local password that has not changed in years. The design answer is credential injection: the gateway holds that password in a vault and supplies it into the session without displaying it, so the technician gets in without learning it, and the password outlives their time at the vendor. That converts a device credential problem into a vault problem. It is a better problem to have, but it is not the same as having solved it.
How would scope work for an integrator that covers several of our sites?
Scope is designed as a set of site and system pairs bound to named technicians at that vendor, not as a network range and not as a site-wide grant. The practical consequence is for how you extend coverage: vendor by vendor rather than site by site, because vendor scope often crosses sites while site scope does not cross vendors. Onboarding a vendor once and attaching every site they touch produces a scope list shaped the way the work is actually dispatched. It also makes offboarding a single action, since a technician who leaves that vendor loses every site at once, which is exactly the case a shared credential handles worst.
What happens if the ticket system is unreachable?
This is a decision rather than a default. Fail closed means no ticket lookup, no session, and the emergency route becomes the only way in, which turns an outage in a business system into an access outage at a plant. Fail open with a grace period means recently validated tickets keep working for a defined interval, which means a window in which scope is asserted rather than checked. The design can express either, and it separates two cases that get conflated: validation at session start, where the answer matters, and validation during a session already running, where the sensible behavior is to carry the ticket state captured at the start rather than drop a technician in the middle of a change. The choice belongs to the customer, and it should be made before the situation arrives, not during it.
Where would the recordings and logs live, and who controls them?
The design intent is that recordings, command logs, and file transfer records land in storage you own, inside your environment, with the gateway holding the index rather than the material. Two things follow that are easy to overlook. First, a recorded engineering session captures whatever crosses the screen, which includes the vendor's own proprietary tooling and any password typed in band, so masking rules and credential injection are data handling features and not only access features. Second, the export requirement is worth stating before deployment rather than after: material that can only be read by the product that wrote it is a liability at the moment you most need it, whether that moment is a dispute with a vendor or a change of platform. A neutral video container and structured logs in a documented format are the property to insist on, from us or from anyone else.
What does the customer decide about vendor-owned laptops?
Vendors arrive with their own machines, and there are two designs to choose between. Accept the device and require posture evidence: a device certificate, disk encryption, a minimum OS patch level, an endpoint agent present. That is cheaper for you and depends entirely on the vendor's IT department agreeing to enroll a machine they own into a check you specify, which is a commercial conversation more than a technical one. Or refuse the device and deliver the session to a workstation inside your environment, where the tools run on your image and files land in a path you control. That is stronger and moves the cost to you: workstation capacity, licensing for the vendor's software, and often a separate image per vendor, because vendor engineering tools coexist badly on one machine. The gateway is designed to enforce whichever you pick. It cannot make a vendor cooperate with the first.