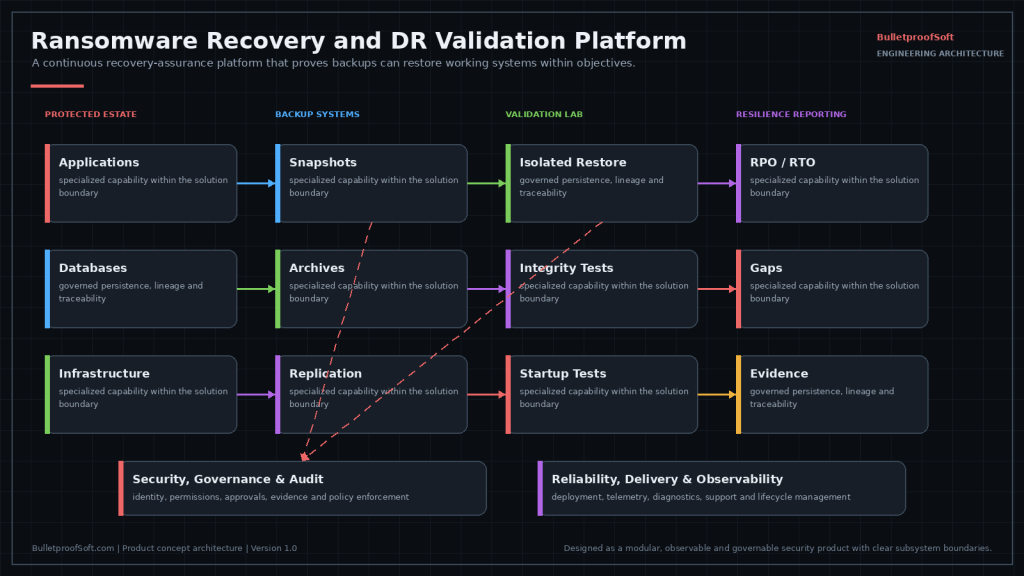
Almost every organisation has backups. Far fewer have ever restored one under pressure, and fewer still can say how long it took or whether the application actually started afterwards. A backup that has never been restored is a hypothesis, and a ransomware incident is a poor time to test it.
Status: product concept, in active development. This is something we are building, not something you can buy today. We publish our roadmap because the engineering thinking behind it is the useful part — and because we would rather show you the design than imply a finished product.
Designed Capabilities
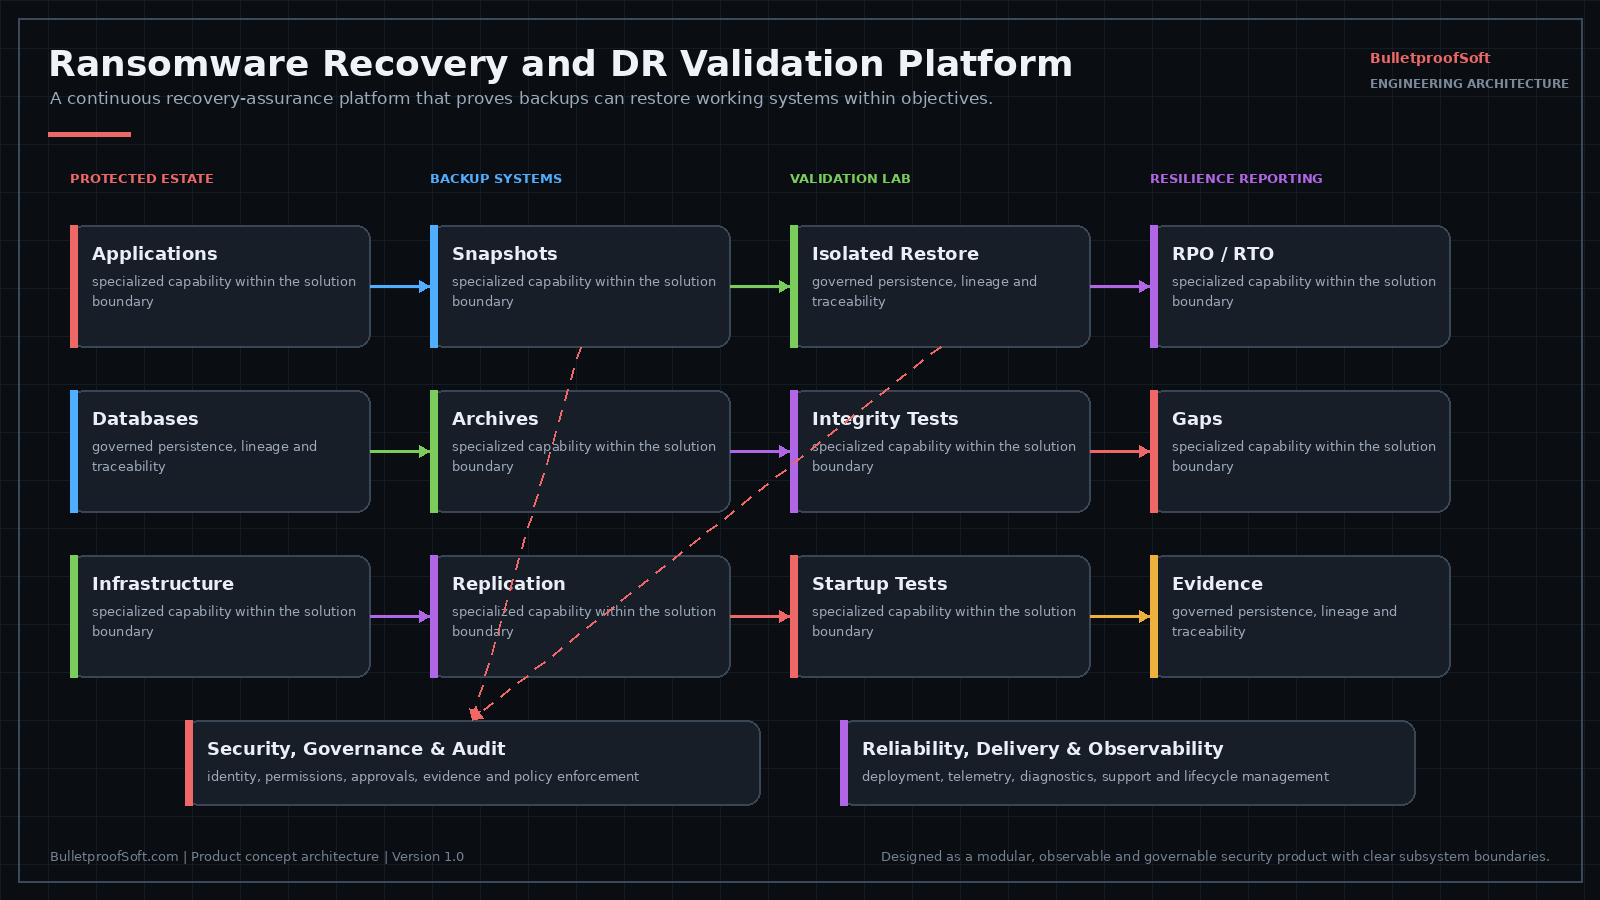
- Backup and recovery-plan inventory — what is protected, and what quietly is not.
- Isolated restore orchestration — real restores into a sealed environment, routinely.
- Integrity and malware checks — confirm you are not restoring the infection.
- Application and dependency startup tests — data restored is not the same as service restored.
- Database consistency validation — the restore is coherent, not merely complete.
- RPO and RTO measurement — measured, not assumed from the policy document.
- Recovery evidence and gap reporting — proof for auditors and insurers.
- Remediation workflow and recurring schedules — gaps become tracked work.
Proof Beats Policy
The point is to replace a stated recovery objective with a measured one. Knowing a critical system restores and starts in four hours — because it was tested last week — is a very different conversation with the board than pointing at a document claiming it should.
Tell us if this matches a problem you have — early input shapes what we build first, and we will give you an honest view of where it stands.
Related services
- Incident Response and Digital Forensics — Recovery starts with containment: incident response and digital forensics.
What Would You Bring Back First?
Recovery plans usually list systems in order of business importance. Recovery itself happens in order of dependency, and the two lists are rarely the same document. Identity comes before the applications that authenticate against it. DNS and certificate services come before nearly everything. Licensing servers, message brokers and shared file services sit underneath applications that look self-contained on an architecture diagram. Working that order out on paper is cheap. Discovering it during an incident, with a tired team and a ringing phone, is not.
Nothing Here Is on Sale Yet
This validation platform is in development. It is not available to purchase, license, or pilot today, and nothing described in the capability list is shipped behavior. We publish the design because the underlying practice, restoring into isolation and measuring what happens, is something you can begin without any product at all.
Immutability Is a Claim You Have to Test
Vendors offer retention locks, object lock, air gaps and immutable tiers, and a feature being enabled is not the same as that feature being effective. The questions worth asking are whether the backup console authenticates against the same directory as the systems it protects, whether an administrator of that console can shorten retention on their own, whether deletion requires a second person, and how you would detect an attempt. Treat backup infrastructure as production, because working backups are what let a victim decline to pay. Any credential able to administer both production and backups undoes much of the design around it.
A Tabletop and a Restore Test Find Different Problems
Discussion exercises surface decision failures. Who declares an incident, who is authorized to approve or refuse a payment, who speaks to customers, whether anyone has phone numbers once the mail system is down. Technical restore tests surface a different class entirely: missing encryption keys, a database that restores but will not start, an application that depends on a license server nobody backed up, a runbook that names a person who left last year. Both are worth running, and neither substitutes for the other.
Insurers and Assessors Ask Different Questions
An auditor asks whether a documented process exists and was followed. An insurer or broker asks what you can demonstrate about recovery capability, and those questions reach into backup isolation and testing detail that a policy document does not answer. How either audience judges what you produce is not ours to promise. What you can control is having dated restore records, measured durations, and a list of known gaps with named owners already in hand rather than assembled against a deadline. That material is the same evidence described on our security compliance readiness page.
If You Have Never Restored Anything, Start Small
Pick one system that matters and restore it into an isolated environment. Time the whole thing end to end, including the hours spent hunting for credentials and waiting on transfers. Try to start the application, not only to recover the data. Write down everything that surprised you, because those surprises are the actual gaps in the plan and they do not turn up in a document review. If an incident is already underway, the containment and evidence questions on our incident response page come first and this work comes after.
Frequently Asked Questions
What is this platform, and what is it not?
It is designed to be a validation layer that sits over the backup, snapshot and replication tools you already run. It is not a backup product: it takes no copies of its own, owns no storage target, and is not meant to replace your backup vendor's console or scheduler. It is not detection tooling either, so it is not an EDR agent, not a SIEM, and not a way to find an intrusion that is currently underway. It is also not intended to become the system of record for your data, which stays in the platforms that already hold it. None of this can be deployed today, because it is still being designed and built rather than sold.
What has to already exist on our side for something like this to be useful?
Four things. Backups that complete, with a catalog that can be read programmatically through a documented API or CLI, since the design is to query job and protection state rather than take custody of the data. A dependency map written at the level of service accounts, certificates, license bindings and DNS names rather than at the level of hosts, because those are the bindings that break on a restored machine. Somewhere to restore into that is separate from production compute and storage, on its own network segment with no return route to production. And a named owner per system in scope, because a validation run nobody is accountable for produces a report and nothing else.
How is a rollout designed to proceed, in order?
The intended sequence starts with reading the backup catalog and recording what is protected and what is not, with no restores at all in that first pass. Then scope and sequence are agreed. Then the restore environment is stood up and its isolation is proven, including that it cannot reach production. Then one attended restore is run end to end by hand, with the platform observing and timing rather than driving. Only after that does the same system go onto an unattended schedule, with the automated checks listed above running against each result. Further systems are added in dependency order, and recurring schedules and reporting are turned on last.
How would it integrate with the systems we already run?
Through the interfaces those systems already expose, and deliberately through the same restore path a real incident would use. The design reads job state and protection status from the backup platform's API or CLI, and issues restores through that platform's own restore interface rather than through a mechanism of its own, because a test that exercises a different code path than the actual recovery proves less than it appears to. Provisioning the isolated environment is designed to go through the hypervisor or cloud API you already operate. Results are meant to leave as structured records over webhook or syslog, so runs and failures land in the ticket system and log platform your team already watches instead of only in another console.
Where does the data go, and what stays under our control?
The restored copy is designed to stay inside your restore environment. What the platform is intended to move is metadata about the run: timings, exit codes, hashes, check results and log excerpts, not the application data itself. That has a planning consequence. A restored copy is production data with the same classification as the original, so the isolated environment inherits the encryption, logging and access controls of the source system rather than being treated as a lab. Malware scanning inside a sealed segment also needs its signatures staged or otherwise reachable there, which is easy to overlook when the segment has no outbound route. Evidence is designed to be exportable in plain formats so the record outlives any one tool.
Would this put load on production or on our backup infrastructure?
Restores are designed to land in the isolated environment, never over a running system, so production servers are not the target. The contention is elsewhere. Reading a backup catalog through an API adds load to the backup server, and a restore pulls from the same repositories, tape or object storage and across the same network links the nightly jobs use. Validation windows therefore have to be chosen against the backup schedule, and large systems may need a throughput budget agreed in advance rather than discovered when a backup job overruns.
What about systems that cannot be restored into an isolated environment at all?
Some cannot be, and the useful answer is to record why. Appliances whose license is bound to a hardware identifier, systems that require a physical dongle, and equipment where the vendor controls the restore process do not come back inside a sealed segment without vendor involvement. Data held in a SaaS platform is usually testable only as an export and reimport, which validates the export rather than the provider's own recovery. The design is to mark these as not validatable by restore, with the reason attached, so the untested set stays visible instead of blending into the tested set.
What would we have to decide, as opposed to provide?
Which systems are in scope and the order they are tested in. How often each one is retested. What counts as a pass for each application, expressed as a check that runs without a person watching a screen, such as a health endpoint returning a known response or a query returning an expected row count. How long the evidence from a run is kept. Who signs off on destroying a restored copy and confirming the destruction happened. How break glass credentials for the recovery environment are stored and who may use them. And whether a failed check stops the rest of a run or lets it continue so the full picture is visible at the end.